Solutions
Whoever runs the interview, the criteria stay the same
Interview scores vary with the interviewer. Decide the questions and evaluation criteria up front, and apply the same conditions to every candidate.
Challenge
The spread in scores is not about interviewer ability
When the criteria are vague, scores drift from interviewer to interviewer. That comes from the interviews not being alike, not from how good the interviewers are.
- Different questions in each interview mean different information collected
- The same answer is weighted differently depending on the interviewer’s experience
- The bar shifts against whoever was interviewed just before
01
Design the criteria
Decide up front what to ask and what to measure
02
Applied to every candidate
No differences in conditions between interviews
03
AI interview
Questions and answers based on the preset questions
04
Score and reasoning
Generated for each criterion
05
Final decision
Your hiring team
The three shaded steps are automated. The pass-or-fail decision is made by a person.
Solution
Decide the criteria first, then interview
Rather than putting an impression into words after the interview, you decide what to measure before it. A score and its reasoning are generated for each criterion and kept on record.
- Every candidate is asked the same questions
- A score and its reasoning remain for each criterion
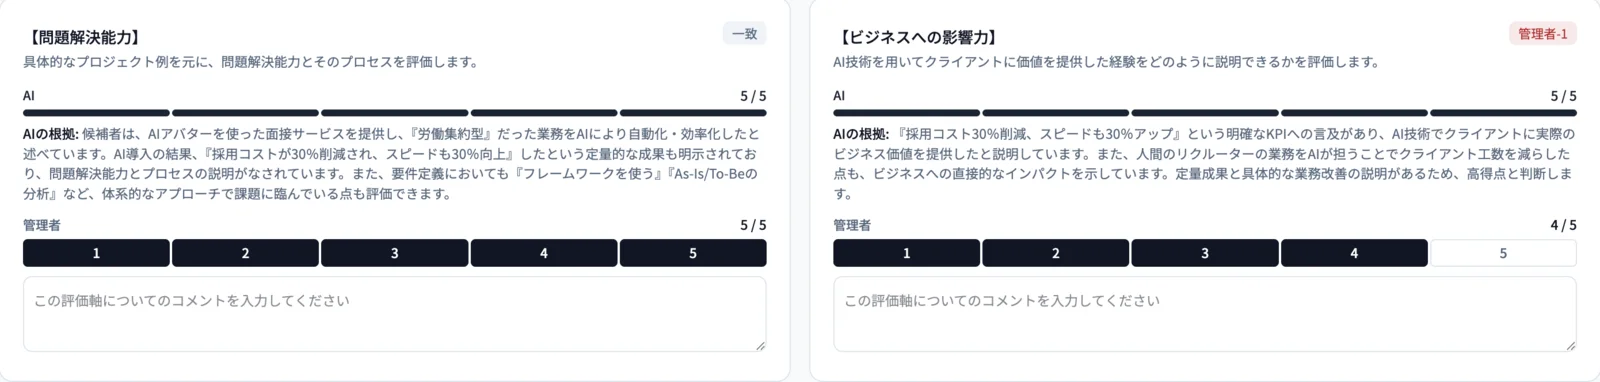
- The AI evaluation and a human one can be recorded side by side
Verification
You can check afterwards whether anything is skewed
Looking at the score distribution per criterion shows which criteria the AI keeps scoring the same way. You can then separate whether the wording of the criterion is vague or the questions do not probe it, and fix the design.
- Review the score distribution per criterion
- Identify criteria with little spread
- Feed it back into the question and criteria design
Show the numbers
| Criterion | 1 pt | 2 pt | 3 pt | 4 pt | 5 pt | Std. dev. | Modal share |
|---|---|---|---|---|---|---|---|
| Intent to stay | 12 | 63 | 68 | 30 | 2 | 0.88 | 39% |
| Communication | 4 | 19 | 64 | 64 | 24 | 0.94 | 37% |
| Adaptability | 7 | 36 | 67 | 49 | 16 | 0.99 | 38% |
| Logical thinking | 9 | 33 | 79 | 37 | 17 | 0.99 | 45% |
| Initiative | 13 | 29 | 62 | 48 | 23 | 1.10 | 35% |
| Domain knowledge | 19 | 44 | 54 | 36 | 22 | 1.18 | 31% |
The figure on each bar is the share taken by the most common score. Criteria are sorted by standard deviation, smallest first.
Related pages
More detail, by topic
Even with shared criteria, scores split over how they are read and how many there are. These columns go further.
When interviewers read the criteria differently, the same answer earns different scores →
Use gaps between human and AI scores to find where readings split, and fix them.
Choose an AI interview by whether it can explain its scoring →
Four questions to check what the AI reads and the standard it scores against.
More criteria do not mean more evidence →
Why scores bunch up, checked against public civil-service rating data.
Frequently asked questions
What information is the evaluation based on?
Evaluation is based on what the candidate says. Non-verbal signals such as facial expression, tone of voice and speaking pace are not used. This follows the direction set by the EU AI Act, the New York City ordinance and similar rules limiting emotion inference and non-verbal assessment.
Does the AI decide who is hired?
No. The AI can indicate a pass, but our position is that a rejection is decided by a person. The score is input to the decision; your hiring team makes it.
If a candidate asks why they were rated that way, can we answer?
The score for each criterion is kept along with written reasoning. The interview recording and transcript are stored too, so you can trace it back later.
Can it be compared with a human interviewer’s evaluation?
Yes. The AI evaluation and a human reviewer’s can be recorded side by side. The overall score and the gap on each criterion are shown, so you can see where the two diverged.
Start the conversation with the criteria themselves
We will show how your current standards translate into questions and evaluation criteria. Free, about 30 minutes.